I tested DeepSeek V4 Flash 0731 on everyday coding tasks. It handled focused edits well, but I still preferred larger models for complex, one-pass changes across a project. This is a field note from August 2026, not a general benchmark.
What Shipped
On July 31, 2026, DeepSeek announced the V4 Flash API release in public beta. The API kept the same base URL and used deepseek-v4-flash as the model name. DeepSeek also released the 0731 weights under the MIT License.
The official model page lists a 1M context window. DeepSeek said the July 31 update applied to the Flash API; Pro and the app and web models were unchanged at that time.
Read the Benchmarks Carefully
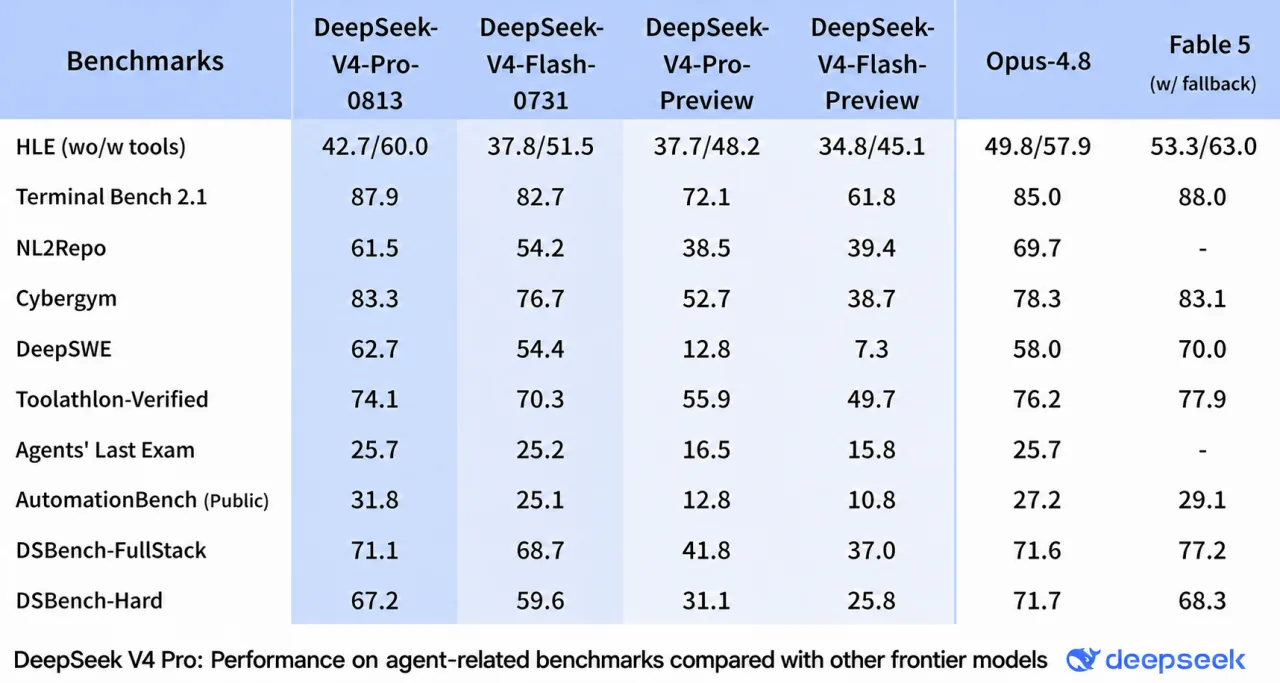
DeepSeek reports 82.7 on Terminal-Bench 2.1, 54.4 on DeepSWE, and 76.7 on Cybergym. It ran the public code-agent tests with an unreleased minimal DeepSeek Harness configuration at max effort.
Treat these as vendor-reported results under a specific harness, not a prediction for your workload. Agent benchmarks are sensitive to the tools, prompts, limits, and scaffolding around the model.
Check Current Pricing
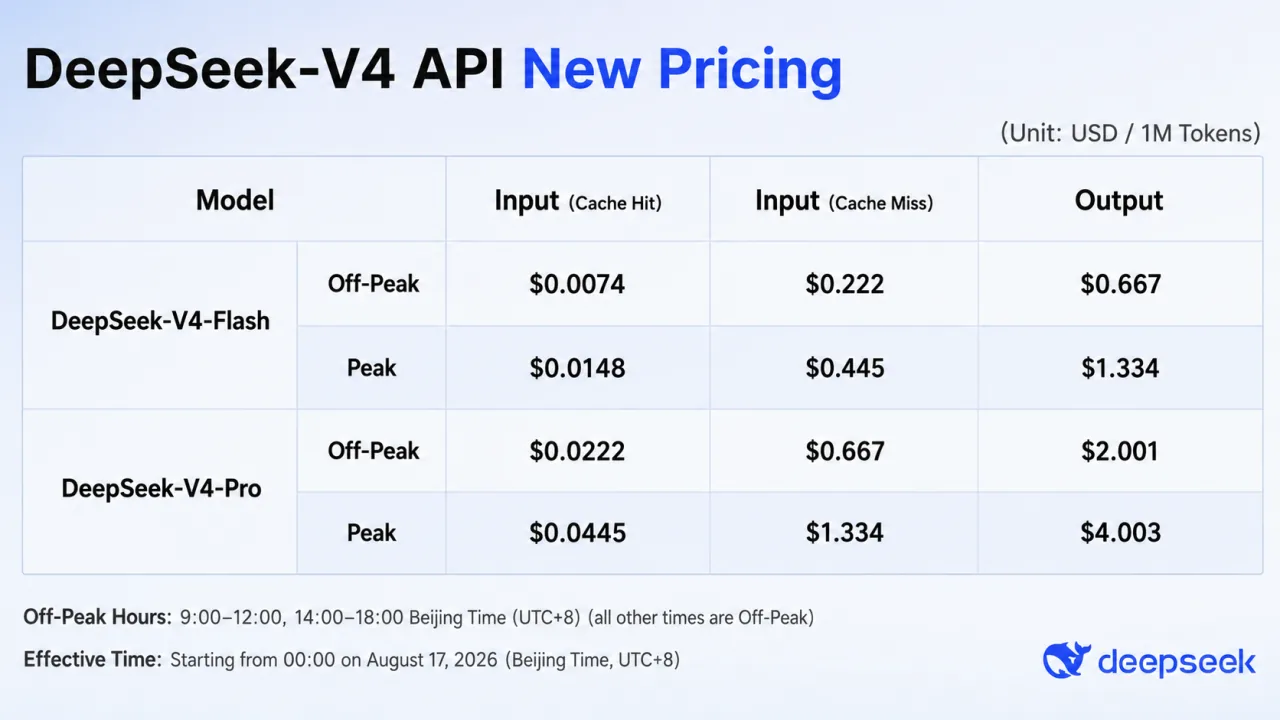
DeepSeek has changed V4 pricing and peak-hour rules since the 0731 release. Check the current official pricing page before estimating workload cost. Compare models with the same prompt, harness, cache conditions, and output length.
Where It Fits
I would use V4 Flash for focused coding tasks where cost and throughput matter, then route ambiguous refactors or critical reviews to a stronger model. Run your own tasks through both before setting a default.