Free Muse Spark 1.3 in Cline, With Chrome MCP on Your Existing Session
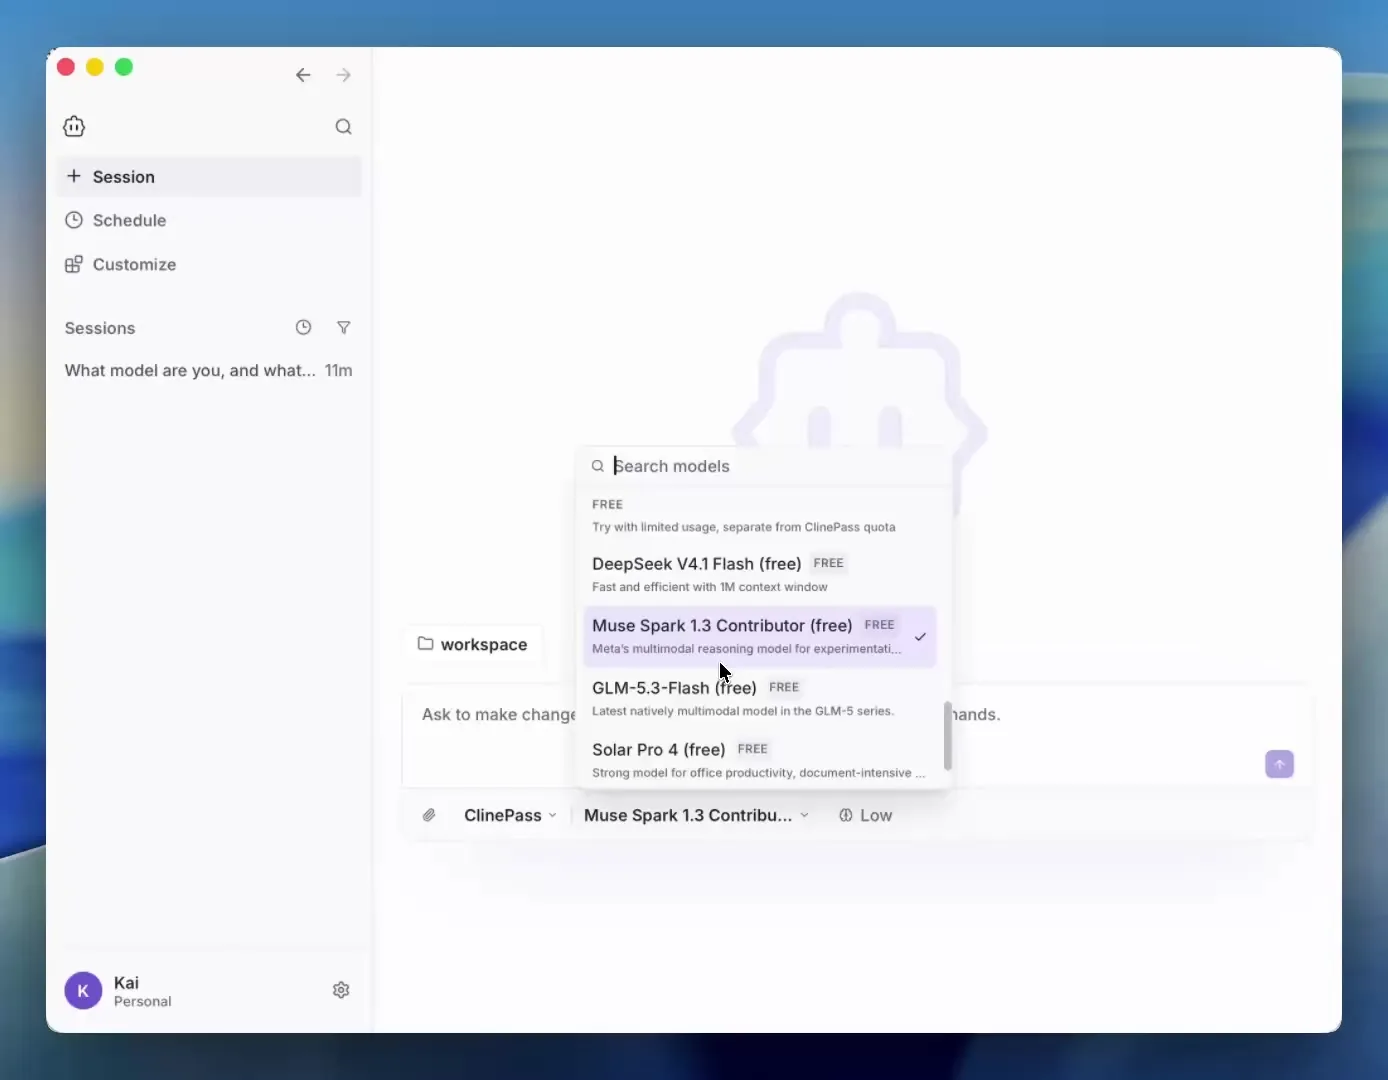
Cline lists Muse Spark 1.3 Contributor, DeepSeek V4.1 Flash, and GLM-5.3-Flash as free. I tested Spark with Chrome MCP on my logged-in browser.
Read articleTopic Pillar & Hub
Real-World Benchmarks, LLM Reviews, and Developer Tooling for AI Engineers
No synthetic benchmarks - only hands-on tests in real repositories. We test frontier models (Claude Opus/Fable, GPT-5.6 Sol, Kimi k3, GLM-5.3, Grok 4.6/4.7) against production codebases.
Evaluating models on full-stack web, 3D graphics (Three.js), and backend microservices.
Identifying which models excel at routine refactoring vs complex architectural reasoning.
Testing terminal tools, IDE extensions, and browser-automation engines.
Use fast/cost-effective models for generation and frontier models for reasoning & architecture.
Never rely on public leaderboards; benchmark on your own internal test harness.
Low latency, high instruction following fidelity, concise tool calling, and resilient recovery when compiler errors occur.
Field Reports & Case Studies
Cline lists Muse Spark 1.3 Contributor, DeepSeek V4.1 Flash, and GLM-5.3-Flash as free. I tested Spark with Chrome MCP on my logged-in browser.
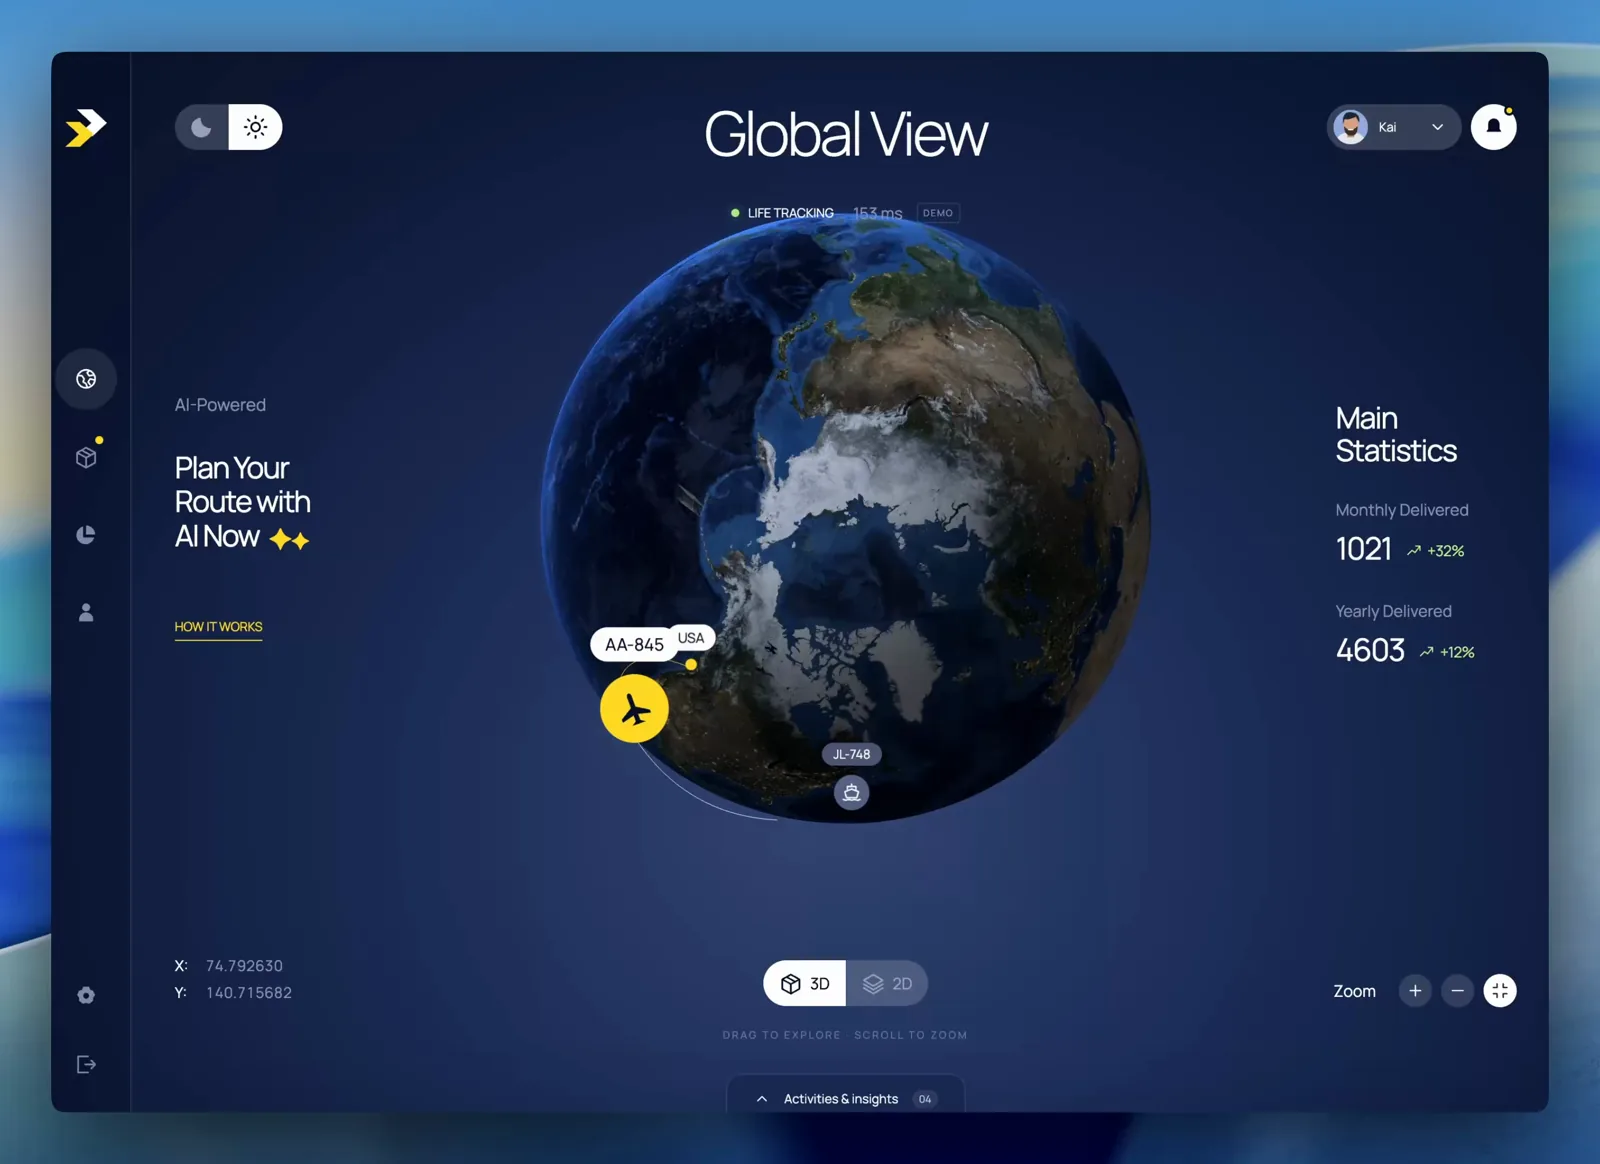
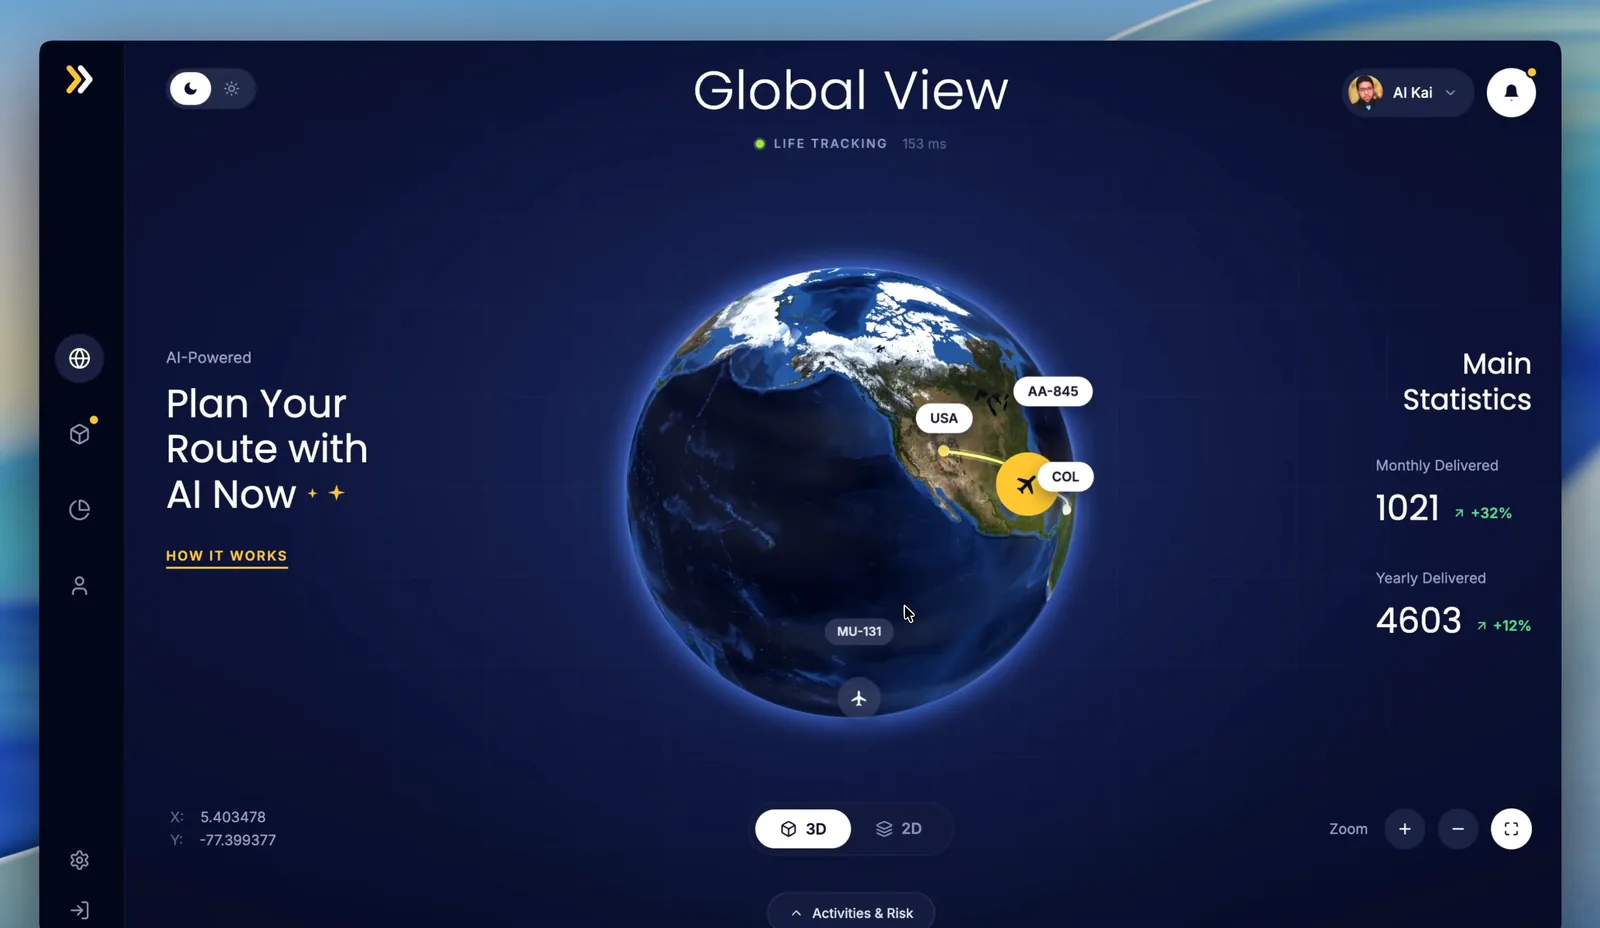
Read articleI ran GPT-6 Astra on a static Three.js logistics dashboard. One prompt, a collapsed activity drawer, and a live demo at hqman.me/demo/gpt-6-astra-3d-globe.
Read articleUse CLIProxyAPI and Cloudflare Tunnel to keep OpenAI models in Cursor after the proposed November 12, 2026 cutoff, with setup and security caveats.
Read articleOpenAI plans to end Cursor's direct model access on November 12, while Anthropic says it will keep supporting Claude in Cursor.
Read articleTencent's Hy4 preview is an open-source 770B MoE model with a 1M-token context window. WorkBuddy and CodeBuddy offer it free for two weeks.
Read articleBuild a dedicated Grok Bot that automatically researches, filters, and delivers a high-signal AI news digest every morning as a clean HTML page.
Read articleGrok Build brings Grok 4.6 to the terminal with native Browser Use plugin support for web automation, testing, and full-stack coding workflows.
Read articleOx Alpha GLM is a new Z.ai GLM iteration. I still guess GLM-5.3 Flash because this stealth model takes images and video, unlike GLM 5.2 in my tests.
Read articleI ran Ox Alpha in OpenCode on my 3D globe test. One prompt, a working Three.js page, and a live demo at hqman.me/demo/ox-alpha-3d-globe.
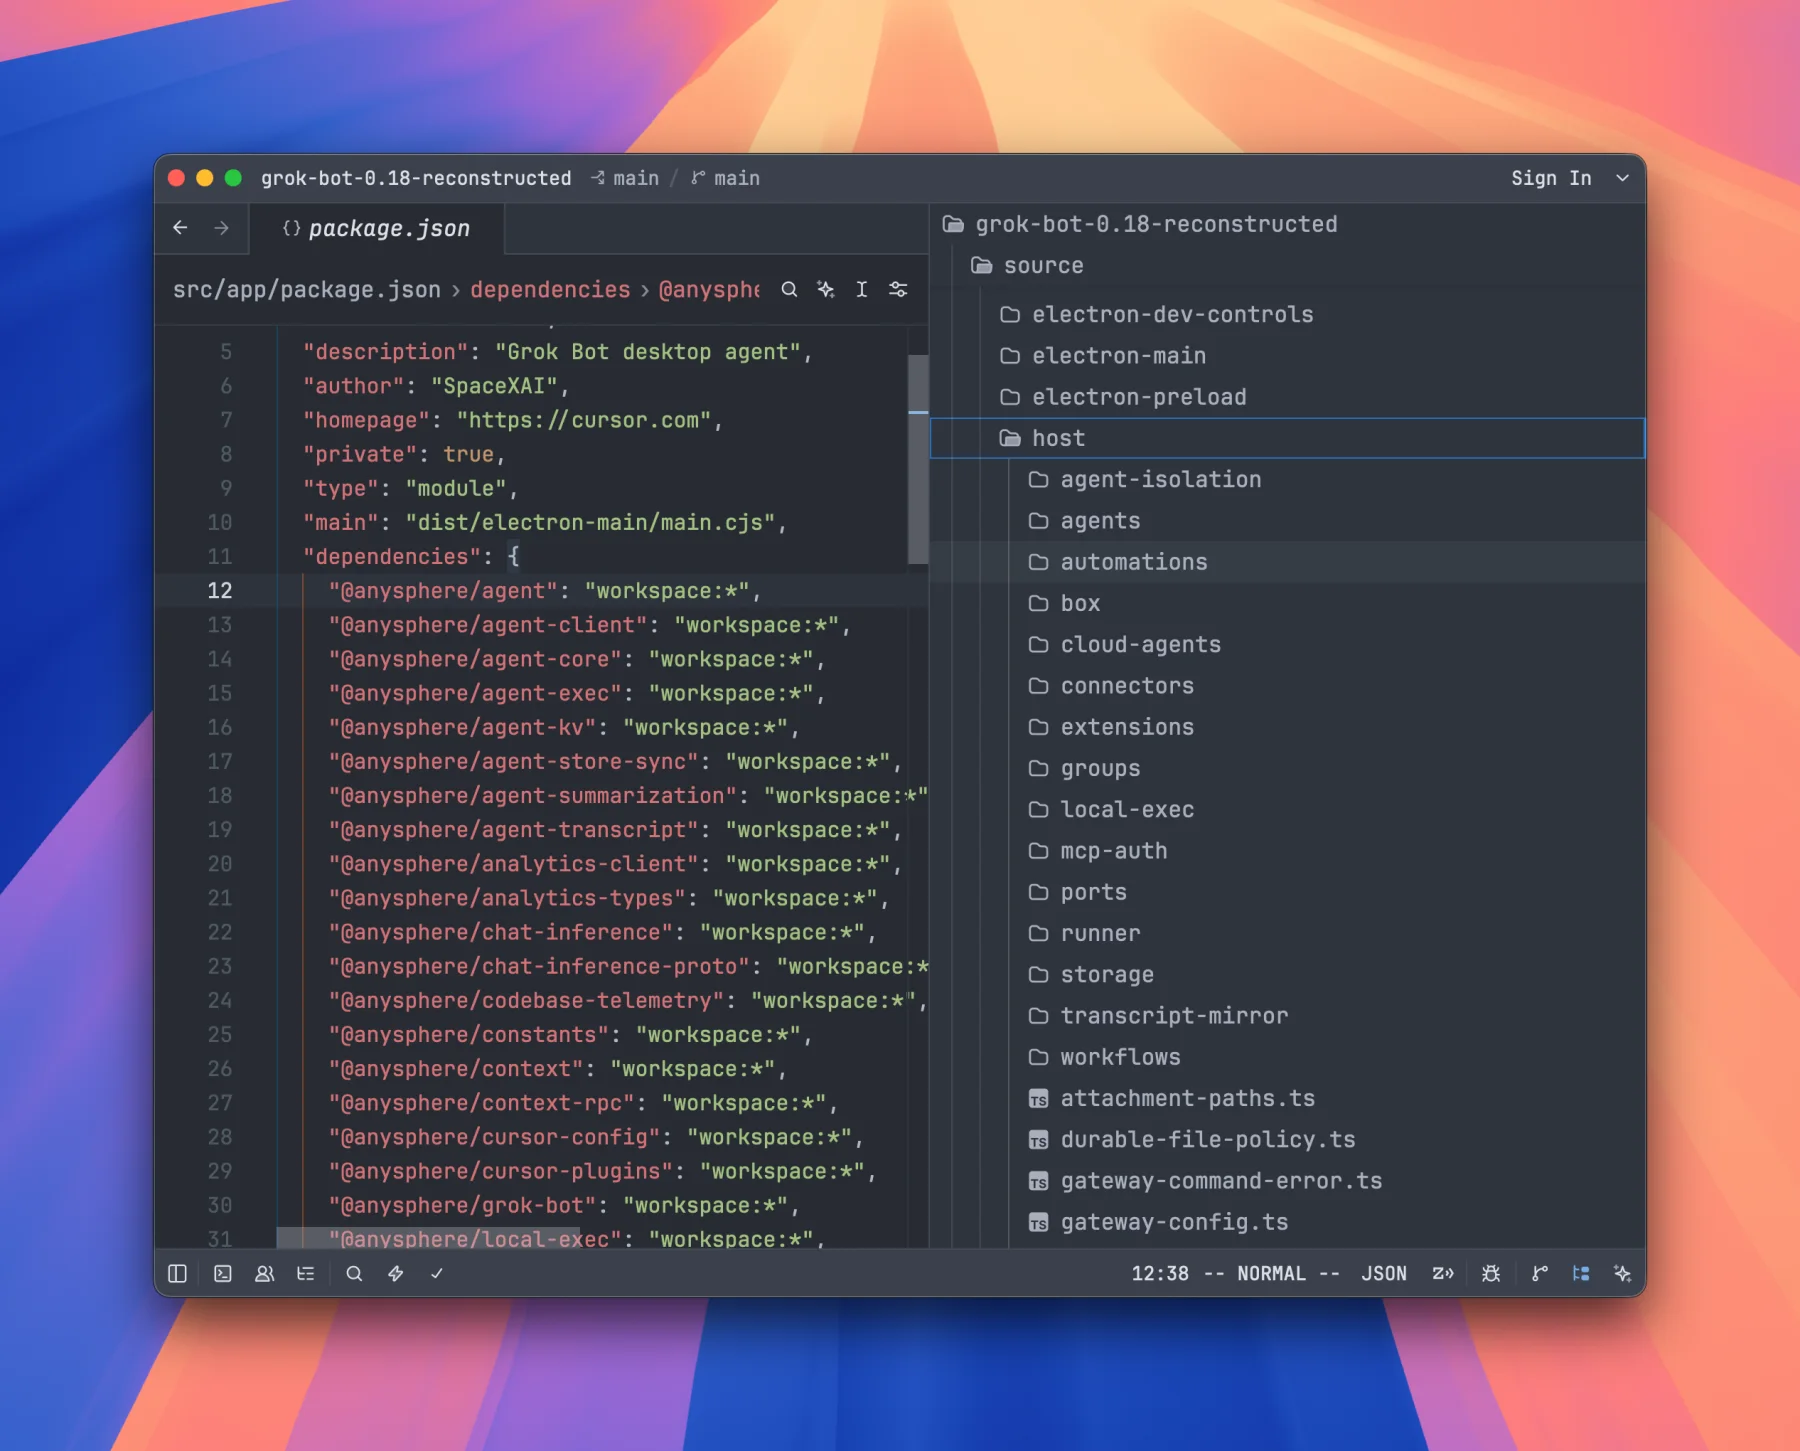
Read articleA source-map mistake exposed enough of Grok Bot 0.18.0 to reconstruct its runtime, prompts, tools, and model routing.
Read articleCursor Origin combines Git hosting, review, collaboration, and agent-focused conflict handling in a beta platform designed for parallel coding agents.
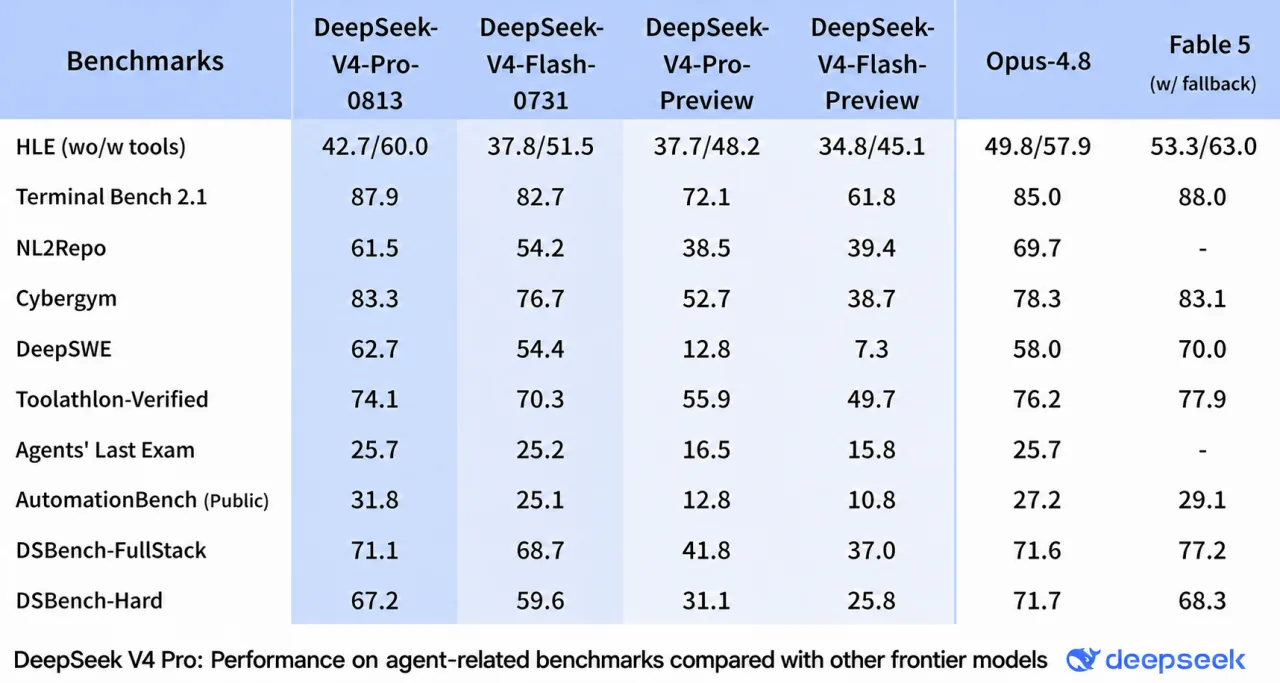
Read articleA hands-on look at DeepSeek V4 Flash 0731, its vendor-reported agent benchmarks, and the coding tasks where I would use it.
Read articleUse ModLens to route screenshots and image files through a configured vision engine, then return structured evidence to a text-only coding agent.
Read articleInstall an Unsloth GGUF build of Qwen3.8-27B with Ollama or llama.cpp, then choose a quant that leaves enough unified memory for the runtime.
Read articleSame model, different inference stack, wildly different latency and cost. Modular's handbook covers VRAM math, KV cache, batching, and serving.
Read articleHow img2threejs turns product photos into editable Three.js code for interactive web demos without a traditional 3D model file.
Read articleGPT-Live can listen and talk at the same time. Drop a Skill or article into ChatGPT and interrupt until the workflow actually clicks.
Read articleSpaceXAI released Grok 4.5 for coding and agents. It is in Cursor on all paid plans, with launch discounts through July 14.
Read articleTencent open-sourced Hy3, a 295B MoE with 21B active parameters. OpenRouter is running it for free until July 21.
Read articleConvert PDFs to Markdown with LaTeX formulas and extracted images on your own machine. MinerU runs offline with OCR for 109 languages.
Read articleA small skill that extracts system structure from an article, writes a JSON spec, and renders an animated GIF with Python and Pillow.
Read articleThird-party GPT-5.5 clients can cap reasoning at 516 tokens. You pay full price and may get a weaker answer.
Read articleA head-to-head frontend test of GLM 5.2 against Opus 4.8, plus Design Arena rankings, pricing, and the caveats that still matter.
Read articleHumanizer is an open-source agent skill that catches 33 AI writing patterns. Pair it with your own voice samples and ship cleaner drafts.
Read articleMiniMax M3 launched with 1M context, near-Opus coding scores, DeepSeek-like API pricing, and two ways to try it immediately.
Read articleRebuild a classroom-ready 3D anatomy viewer with AI-generated images, 3D reconstruction, GLB compression, and a coding agent.
Read article